Overview
Project details
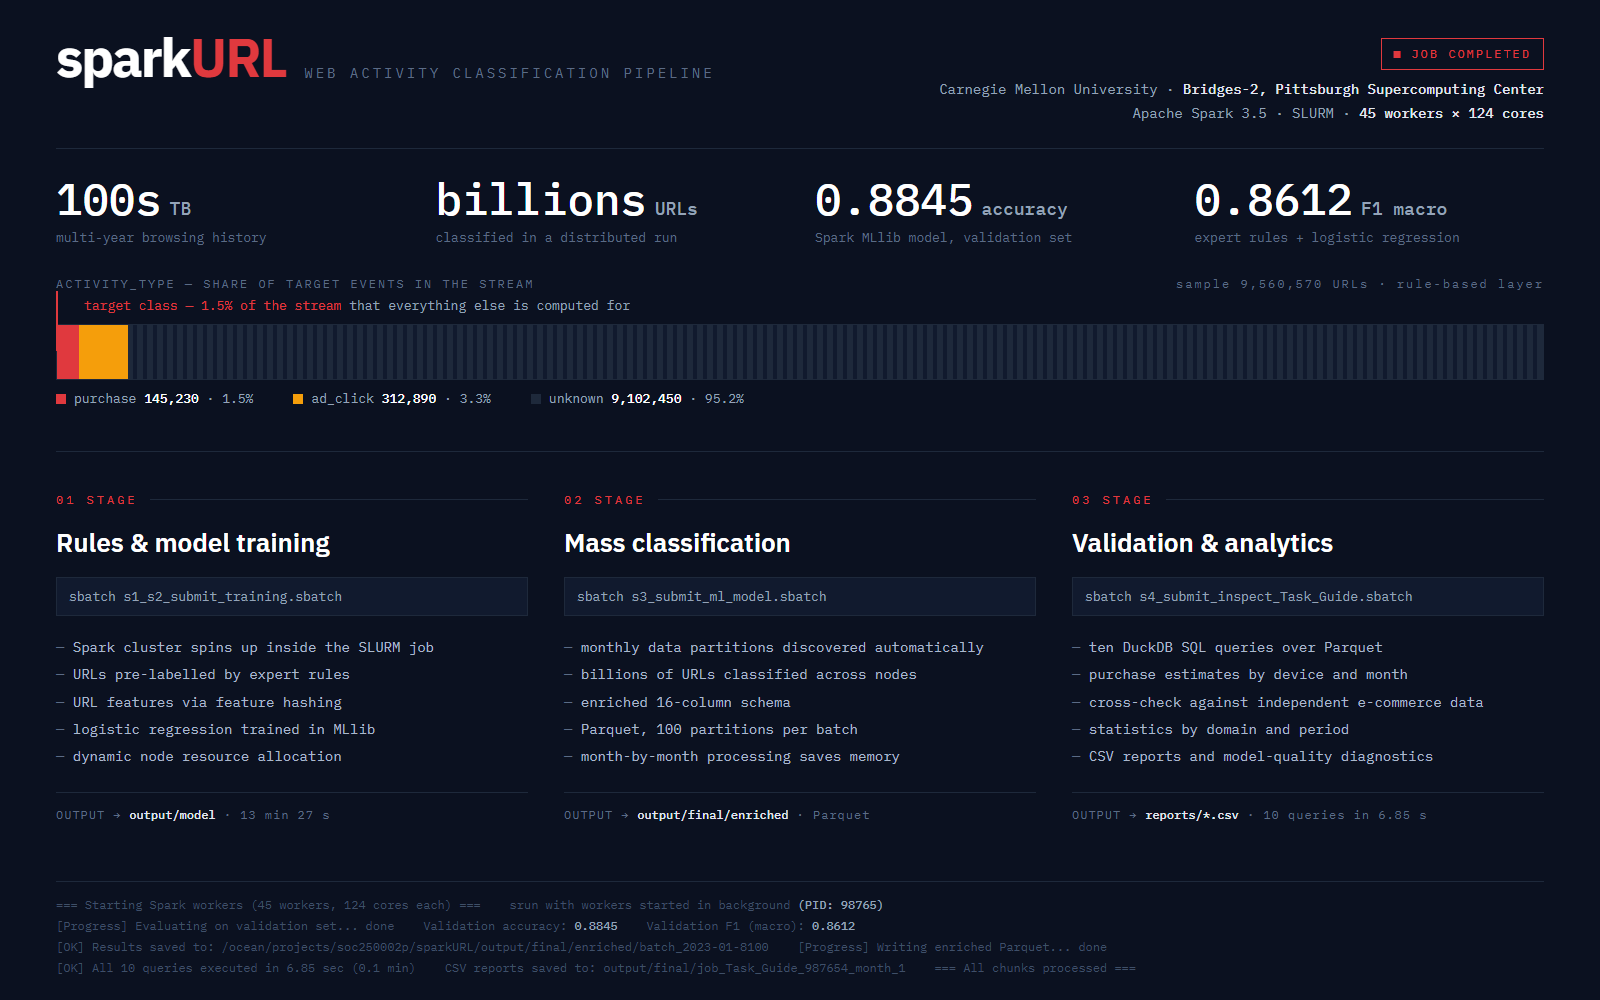
The source data is a multi-year web browsing history spanning hundreds of terabytes and billions of URL records. The pipeline consists of three SLURM jobs.
The first job spins up an Apache Spark cluster inside the job itself, labels URLs with expert rules, extracts features and trains a Spark MLlib model on that labeling (accuracy 0.8845, F1 macro 0.8612). The second discovers new monthly data partitions and classifies billions of URLs at scale, storing enriched datasets in Parquet.
The third computes aggregates in DuckDB: purchase counts by device, domain and period, cross-checked against independent e-commerce data, with a validation report on over- and under-counting. The run used 45 workers of 124 cores each with dynamic resource allocation and is fully reproducible from raw logs to analytical reports.
- Billions of URLs classified
- Model accuracy 0.8845, F1 macro 0.8612
- Bridges-2 supercomputer, 45 workers × 124 cores